The residual as a loss
Turn the equation and its conditions into numbers that are zero only for the solution, add them up, and minimise. Everything else in a PINN is detail, but the details decide whether it works.
Part 1 ended with a training loop that does not care what its loss means (Section 3.6). Part 2 supplied the two things a physics loss needs: the equation in residual form (Section 4.1) and the derivatives of a network with respect to its inputs (Chapter 5). This section puts them together. It is the definition of a physics-informed neural network, and the rest of the book builds on it.
The loss, term by term
Take a problem in the form of Chapter 4: an equation $\mathcal{N}[u] = f$ on a domain $\Omega$, and conditions $\mathcal{B}[u] = g$ on its boundary $\partial\Omega$ (for time-dependent problems the initial condition is one of them). Replace the unknown $u$ by a network $u_\theta$. Then define three kinds of residual:
- the equation residual at a point $\mathbf{x}$ inside the domain, $r_\theta(\mathbf{x}) = \mathcal{N}[u_\theta](\mathbf{x}) - f(\mathbf{x})$;
- the condition residual at a point on the boundary, $b_\theta(\mathbf{x}) = \mathcal{B}[u_\theta](\mathbf{x}) - g(\mathbf{x})$;
- the data residual at a measurement, $u_\theta(\mathbf{x}_k) - d_k$, when there are measurements.
Each is zero where the network does what it should. The PINN loss is a weighted sum of their mean squares over sets of points:
$$\mathcal{L}(\theta) = w_\text{eq}\,\frac{1}{N_r}\sum_{i=1}^{N_r} r_\theta(\mathbf{x}_i)^2 + w_\text{bc}\,\frac{1}{N_b}\sum_{j=1}^{N_b} b_\theta(\mathbf{x}_j)^2 + w_\text{data}\,\frac{1}{N_d}\sum_{k=1}^{N_d}\bigl(u_\theta(\mathbf{x}_k) - d_k\bigr)^2 .$$
The interior points $\mathbf{x}_i$ are the collocation points. The weights $w$ are the numbers the Studio's Loss block asks for. This is the formulation of Raissi et al. (2019), and it is all there is to the idea: training with this loss looks for a network that satisfies the equation, the conditions and the data at once.
Each term catches a different mistake
Before any network is trained, it helps to evaluate the loss on functions we can write down. Take the problem of Section 13.1, $u'' = f$ with $f = -\pi^2\sin(\pi x)$ and $u(0) = u(1) = 0$ (the Studio's sign convention), whose solution is $\sin(\pi x)$, and four candidates:
import math
import torch

def d(y, x):
    return torch.autograd.grad(y, x, torch.ones_like(y), create_graph=True)[0]

f = lambda x: -math.pi**2 * torch.sin(math.pi * x)
candidates = {
    "sin(pi x)   (the solution)": lambda x: torch.sin(math.pi * x),
    "4x(1 - x)                 ": lambda x: 4 * x * (1 - x),
    "0.9 sin(pi x)             ": lambda x: 0.9 * torch.sin(math.pi * x),
    "sin(pi x) + 0.1           ": lambda x: torch.sin(math.pi * x) + 0.1,
}

torch.manual_seed(0)
x_col = torch.rand(1000, 1, dtype=torch.float64, requires_grad=True)     # collocation points
x_bc = torch.tensor([[0.0], [1.0]], dtype=torch.float64)                 # the two boundary points

print("candidate                    equation term   boundary term")
for name, u in candidates.items():
    r = d(d(u(x_col), x_col), x_col) - f(x_col)
    print(f"{name}   {(r**2).mean().item():12.3e}   {(u(x_bc)**2).sum().item():12.3e}")
candidate                    equation term   boundary term
sin(pi x)   (the solution)      3.437e-31      1.500e-32
4x(1 - x)                       1.226e+01      0.000e+00
0.9 sin(pi x)                   4.913e-01      1.215e-32
sin(pi x) + 0.1                 3.437e-31      2.000e-02
Only the solution makes both terms zero. The parabola $4x(1-x)$ looks much like $\sin(\pi x)$ in a plot and satisfies the boundary conditions exactly, but its curvature is the constant $-8$, and the equation term says so loudly. The shifted sine has exactly the right curvature everywhere and is caught by the boundary term alone. The scaled sine is caught by the equation term, more gently. Neither term on its own singles out the solution: the equation has a whole family of solutions (Section 4.1), and the conditions pick one (Section 4.2).
What the sums estimate
The equation term is an average over random points, and averages over random points estimate integrals. As the number of points grows,
$$\frac{1}{N_r}\sum_{i=1}^{N_r} r_\theta(\mathbf{x}_i)^2 \;\longrightarrow\; \frac{1}{|\Omega|}\int_\Omega r_\theta(\mathbf{x})^2\,d\mathbf{x},$$
which is zero only when the residual is zero everywhere (for a continuous residual). That is the reason to trust the loss at all. The estimate is noisy, with a spread that falls like $1/\sqrt{N_r}$, as for the mini-batch gradients of Section 3.3. Here is the equation term of the parabola, estimated twenty times with fresh points at each size:
r2 = lambda x: (-8 + math.pi**2 * torch.sin(math.pi * x)) ** 2      # the parabola's squared residual
xs = torch.linspace(0, 1, 200001, dtype=torch.float64)
print(f"the integral itself: {torch.trapezoid(r2(xs), xs).item():.4f}")

for N in [10, 100, 1000, 10000, 100000]:
    estimates = torch.tensor([r2(torch.rand(N, generator=torch.Generator().manual_seed(s), dtype=torch.float64)).mean()
                              for s in range(20)])
    print(f"N = {N:6d}:  mean of 20 estimates {estimates.mean():.4f},  spread {estimates.std():.4f}")
the integral itself: 12.1736
N =     10:  mean of 20 estimates 10.3118,  spread 3.5178
N =    100:  mean of 20 estimates 12.1201,  spread 2.0793
N =   1000:  mean of 20 estimates 12.3023,  spread 0.4270
N =  10000:  mean of 20 estimates 12.1891,  spread 0.1341
N = 100000:  mean of 20 estimates 12.1874,  spread 0.0594
With ten points the estimate can be off by a third; with ten thousand it is good to about one per cent. The practical meaning is that a PINN's loss is a measurement of how well the equation holds, made with a finite number of probes, and Chapter 7 is about where to put them.
Zero at the points is not zero everywhere
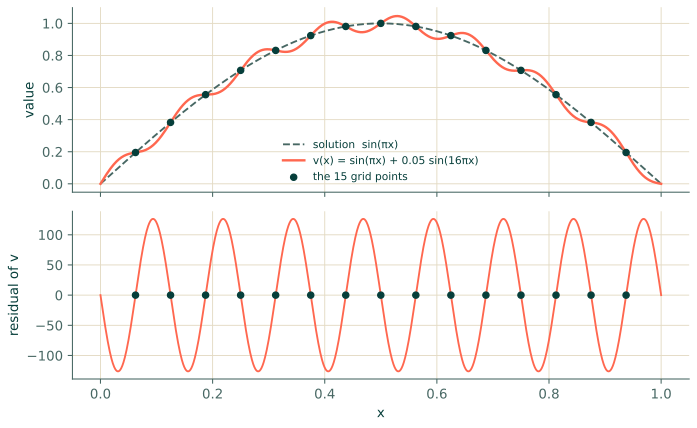
A finite set of points can also be fooled outright. Put the collocation points on a regular grid, $x_i = i/16$, and consider $v(x) = \sin(\pi x) + 0.05\sin(16\pi x)$. The extra term vanishes at every grid point and at both ends, and so does its contribution to $v''$, because $\sin(16\pi i/16) = \sin(i\pi) = 0$:
v = lambda x: torch.sin(math.pi * x) + 0.05 * torch.sin(16 * math.pi * x)
x_grid = torch.linspace(0, 1, 17, dtype=torch.float64)[1:-1].reshape(-1, 1).requires_grad_(True)
x_rand = torch.rand(1000, 1, dtype=torch.float64, requires_grad=True)

for name, pts in [("on the 15 grid points  ", x_grid), ("on 1000 random points  ", x_rand)]:
    r = d(d(v(pts), pts), pts) - f(pts)
    print(f"equation term {name}: {(r**2).mean().item():.2e}")
xt = torch.linspace(0, 1, 1001, dtype=torch.float64)
print(f"boundary term: {(v(x_bc)**2).sum().item():.1e};  largest error against sin(pi x): {(v(xt) - torch.sin(math.pi * xt)).abs().max():.3f}")
equation term on the 15 grid points  : 7.21e-26
equation term on 1000 random points  : 7.87e+03
boundary term: 6.0e-34;  largest error against sin(pi x): 0.050
On the grid the loss is zero to rounding, and the function is wrong by 5% of its height. Between the grid points its residual is enormous, which a thousand random points see at once (Figure 6.1). A network is a smooth function with no particular reason to wiggle at the grid's frequency, so in practice the danger is milder than this, but the lesson stands: the loss only measures the equation where you look. Two habits follow, both developed later: check the residual at points the network did not train on (Section 6.5), and do not let a fixed small set of points be the only place you look (Section 7.1).
What is different from a classical solver
A finite-difference or finite-element solver also turns an equation into conditions at a finite set of points, so the resemblance is real. Three differences make a PINN what it is.
- The unknown is a network, not a table of nodal values. Every weight affects the function everywhere, so the conditions at all points are coupled through the weights, not through a sparse stencil.
- The derivatives are exact for that network (Chapter 5), at any point, with no mesh.
- The equation is satisfied by minimisation, not by solving a system. A finite-difference solver makes its residual exactly zero at its nodes in one linear solve; a PINN drives its residual towards zero by gradient descent and stops somewhere above it. How far above, and why, is the subject of Part 4.
Where this goes in the Studio
The Loss block assembles exactly this sum: one mean square per PDE residual, per BC block and per IC block, each with its weight (PDE weight, BC weights, IC weights). The Studio has no data term yet; Section 8.3 adds one in code.
Exercises
- For the candidate $u = 0.9\sin(\pi x)$, compute the equation residual by hand. Check that its mean square over $[0, 1]$ is about the number in the first table.
- Why can the equation term alone never pick out the solution of a boundary-value problem?
- In the grid example, would 16 random points have caught $v$? Would a regular grid of 17 interior points (spacing $1/18$)?
Answers
- $u'' = -0.9\pi^2\sin(\pi x)$, so $r = u'' - f = 0.1\pi^2\sin(\pi x)$. Its mean square over $[0, 1]$ is $0.01\pi^4 \cdot \tfrac12 \approx 0.487$, close to the $0.491$ estimated from 1000 random points.
- Adding any solution of the homogeneous equation (here $A + Bx$, Section 4.2) leaves the residual unchanged. Only the conditions remove that freedom.
- Random points would almost surely land between the zeros of $\sin(16\pi x)$ and see the residual. On the grid with spacing $1/18$ only one point, $x = 1/2$, falls on a zero, so it too would catch this particular $v$; but a different $v$, built on that grid's own spacing, would fool it. The weakness is a fixed regular set, whatever its size.
Recap
- A PINN replaces the unknown by a network and minimises a weighted sum of mean squared residuals: the equation at collocation points, the conditions on the boundary, and the data, if any.
- Each term catches a different kind of mistake, and only the solution makes them all zero.
- The sums are noisy estimates of integrals, and a fixed set of points can be fooled. Check the residual where the network did not train.
References
- Raissi, M., Perdikaris, P., & Karniadakis, G. E. (2019). Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations. Journal of Computational Physics, 378, 686–707. doi:10.1016/j.jcp.2018.10.045